
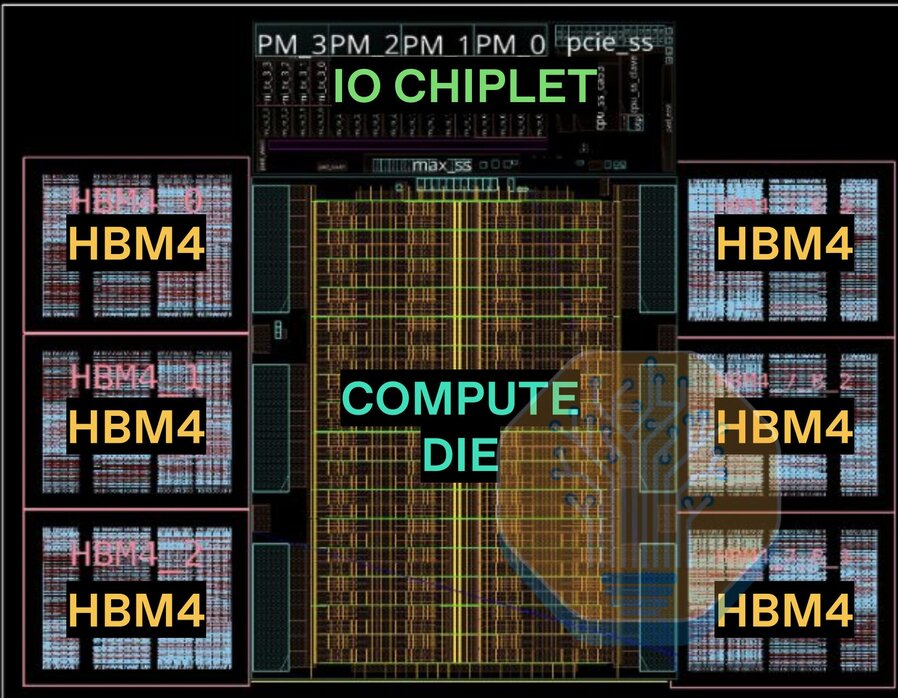
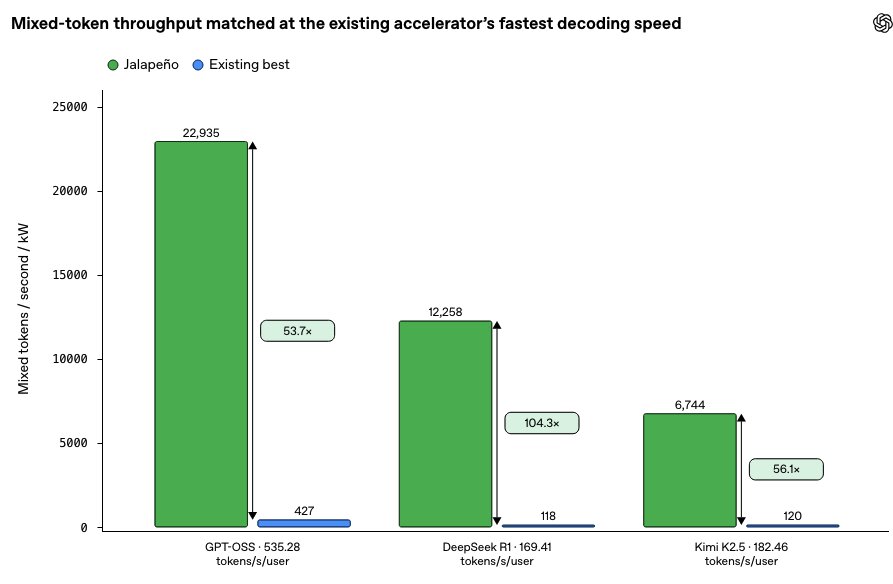
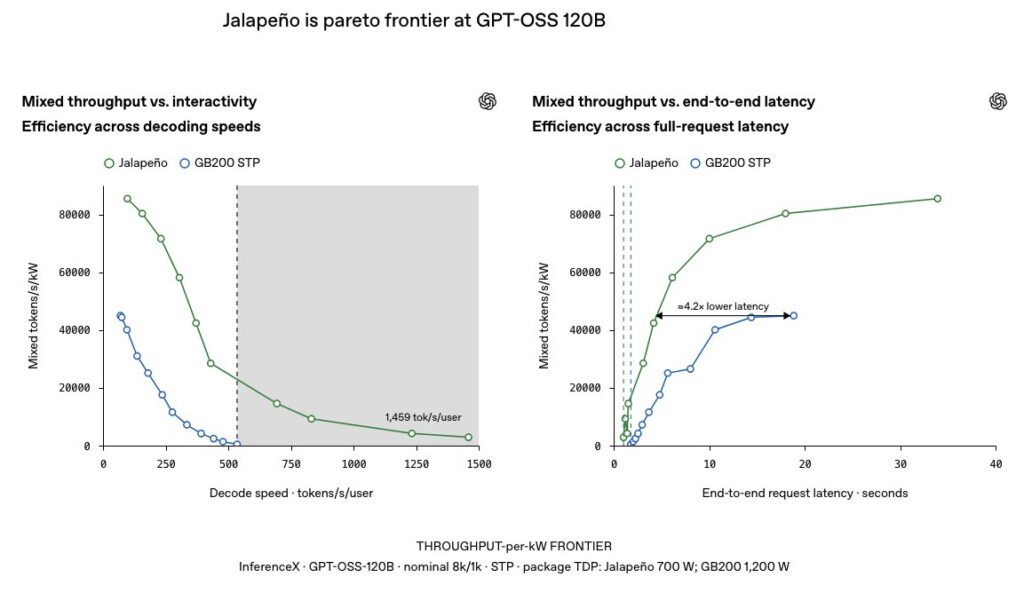
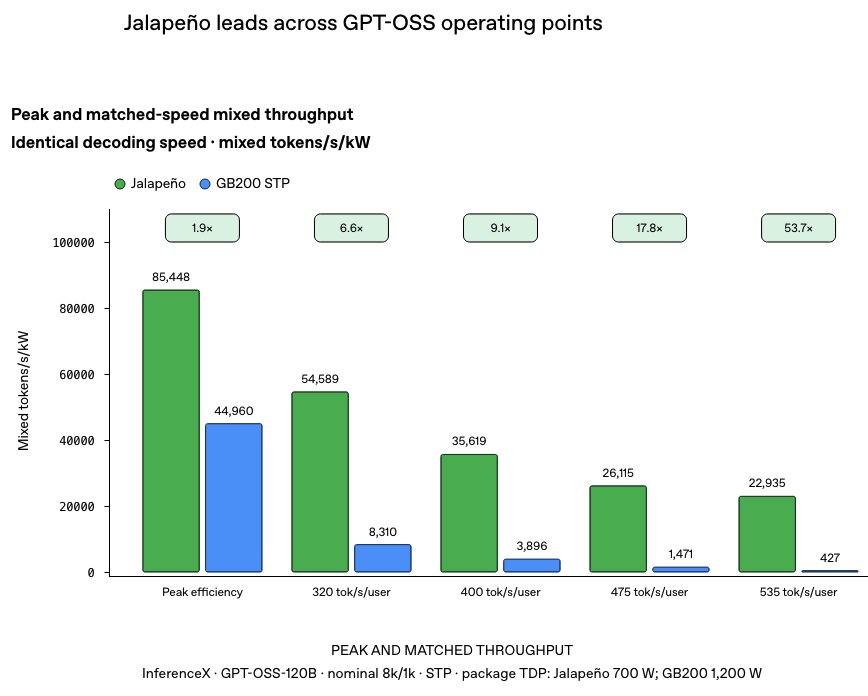
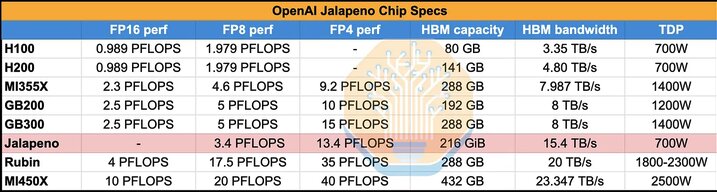
OpenAI Jalapeño chip delivered 1.5 to 1.9 times more AI work per watt at peak throughput and 1.7 to 3.6 times lower end-to-end latency than the comparison systems. For highly interactive workloads, it delivered 2.1 to 4.1 times higher performance.
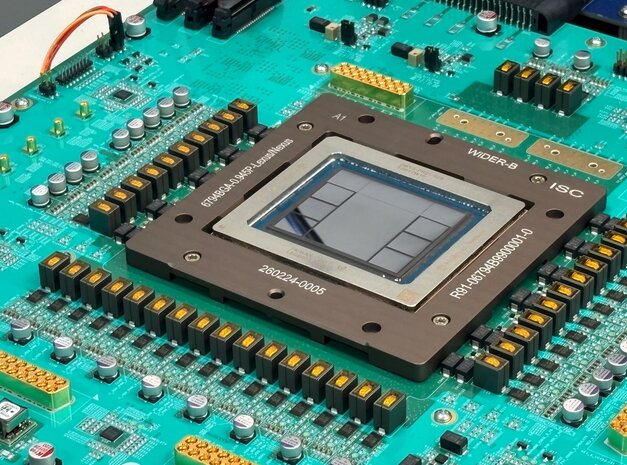
In June, OpenAI unveiled the chip program in partnership with Broadcom, built from a blank slate exclusively for LLM inference. Design work began in the middle of 2024, going from initial team hiring to manufacturing tape-out in ~16 months, an extremely fast ASIC development cycle.
Semianalysis thinks the comparison to Blackwell is somewhat incomplete and unfair. Jalapeño is really competing against chips like Rubin that also use HBM4. Vera Rubin systems are starting to ship to customers now. OpenAI has to scale beyond engineering samples of Jalapeño.
Vera Rubin NVL72 delivers 5.4x the perf/MW of GB200 NVL72
Brian Wang is a Futurist Thought Leader and a popular Science blogger with 1 million readers per month. His blog Nextbigfuture.com is ranked #1 Science News Blog. It covers many disruptive technology and trends including Space, Robotics, Artificial Intelligence, Medicine, Anti-aging Biotechnology, and Nanotechnology.
Known for identifying cutting edge technologies, he is currently a Co-Founder of a startup and fundraiser for high potential early-stage companies. He is the Head of Research for Allocations for deep technology investments and an Angel Investor at Space Angels.
A frequent speaker at corporations, he has been a TEDx speaker, a Singularity University speaker and guest at numerous interviews for radio and podcasts. He is open to public speaking and advising engagements.