

Recursive Language Models (RLMs) are a general inference paradigm that treats long prompts as part of an external environment and allows the LLM to programmatically examine, decompose, and recursively call itself over snippets of the prompt. RLMs can successfully process inputs more than an order of magnitude beyond model context window limits and, even for shorter prompts, dramatically outperform the quality of vanilla frontier LLMs and common long-context and coding scaffolds.
RLM converts semantic work into symbolic work. Instead of the model reasoning about a million tokens in latent space, it writes a Python program that operates over those tokens as a variable, with sub-model calls as function calls. Programs run or they don’t. Loops either cover all the data or they don’t.
This is a mechanism for moving work up the verification hierarchy rather than accepting where it sits. IF it generalizes, it is a credible attack on a main Recursive Self Improvement constraint rather than a workaround for it.
There is this well-known but difficult to characterize phenomenon in language models (LMs) known as “context rot”. This system seems like a clear fix for context rot. BUT it could be a lot, lot more.
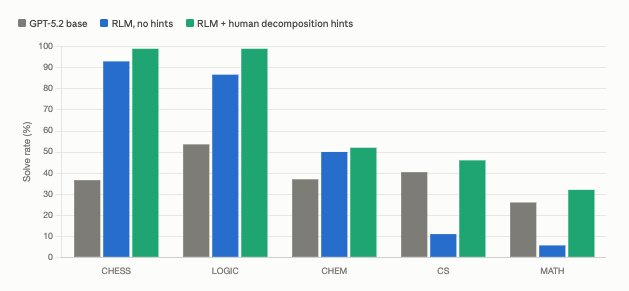
RLM wins where a problem factors into independently-checkable subproblems but loses where reasoning is holistic.
Deciding how to decompose a problem is direction-setting. It is also a programmatic system for taste.
This is Level 1 on a new axis but is not Level 2…YET. It expands p — the verifiable fraction — genuinely and by more than kernel optimization does, because converting semantics to symbols is a category change rather than a speedup. RLM-class techniques plausibly move p from ~0.35 toward 0.45–0.50, which raises the ceiling from ~1.5× to ~1.8–2.0×.
How to tell if they’re a major part of the solution
Falsifiable tests or Areas to Improve
Does a natively-trained RLM at scale beat a scaffolded frontier model? If a Prime Intellect-trained 100B native RLM outperforms Opus 5 in Prime Agent, the axis-of-scale claim is real and this becomes a training-paradigm story rather than a harness story.
Can improvements get refinement showing increasing returns.
Can they fix the MATH and CS splits recover without human hints? This is the direction-setting test. If a trained RLM learns to decompose problems it was not shown how to decompose then the taste bucket is shrinking.
Make it work on non-saturated and non-symbolic benchmarks. Watch RE-Bench, MLE-Bench Lite, and LongCoT MATH specifically.
Train native RLM at scale. If 1,000 samples buys 28% then there could be lot of headroom for big improvement.
MIT License Open source Prime Agent means anyone can work on this. Anyone can check it and work on improving it.
Prime Intellect will actually train native RLMs. They got $130M Series A in July 2026 at a $1B valuation, over $150M total from Radical Ventures, NVIDIA Ventures, and Intel Capital. They own prime-rl and shipped INTELLECT-3, a 100B+ MoE trained on their own RL stack.
What happens if you train a native RLM at frontier scale ? We will know in weeks to months. And there will be many, many attempts to try and to make it work.
Brian Wang is a Futurist Thought Leader and a popular Science blogger with 1 million readers per month. His blog Nextbigfuture.com is ranked #1 Science News Blog. It covers many disruptive technology and trends including Space, Robotics, Artificial Intelligence, Medicine, Anti-aging Biotechnology, and Nanotechnology.
Known for identifying cutting edge technologies, he is currently a Co-Founder of a startup and fundraiser for high potential early-stage companies. He is the Head of Research for Allocations for deep technology investments and an Angel Investor at Space Angels.
A frequent speaker at corporations, he has been a TEDx speaker, a Singularity University speaker and guest at numerous interviews for radio and podcasts. He is open to public speaking and advising engagements.