
Kaplan/Chinchilla scaling laws provide a broad description of the resources needed to improve AI. The measured relationship is that loss falls as a power law in compute: L ≈ L∞ + A·C^(-α), with α somewhere around 0.05–0.07 for language models. Each halving of excess loss costs roughly 10–1000x more compute depending on the exponent.
Converting that into “intelligence or productivity” requires a second function — capability as a function of loss — and nobody has that function. If capability has threshold structure (a model crosses a reliability line and a whole class of tasks flips from 0% to 80%), the same loss curve produces lumpy, much better-looking returns on downstream tasks. Both are observed empirically, in different task families.
Building More Energy and AI Data Centers to Get Better AI
The critical distinction is between shifting the constant A and changing the exponent α. Almost everything that has happened so far moves A.
Things that moved A, roughly:
Algorithmic efficiency: ~3x/year in compute-equivalent terms for pretraining, sustained for a decade across vision and language. This is the big one.
Chinchilla itself is a one-time ~3–4x effective compute gain from correcting the data/parameter ratio — an embarrassing amount of free progress from noticing we’d been reading the curve wrong.
Hardware price-performance: ~1.3x/year in FLOP/$, plus step changes from precision reduction (FP32 → BF16 → FP8 → FP4), each of which is roughly a free doubling.
Sparsity/MoE decoupled parameter count from per-token FLOPs.
Data curation and synthetic data: large, poorly-quantified multipliers.
AI Improvement Staircase
Imagine a staircase where every step is ten times taller than the one before it.
Step one is a foot high. Step two is ten feet. Step three is a hundred. Step four is a thousand.
Each step gets you one unit smarter. That’s the whole scaling law.
Now the two numbers:
A is how strong your legs are. All the progress of the last decade — better chips, better algorithms, cheaper solar — has been leg strength. Get 100× stronger and you climb two more steps. Real, valuable, and then you’re stuck again.
α is how much taller each step is. Nobody has changed this. If you could make each step only twice as tall instead of ten times, the same legs would carry you thirty steps instead of two.
Strength gets you a few more steps. Changing the step height changes the staircase.
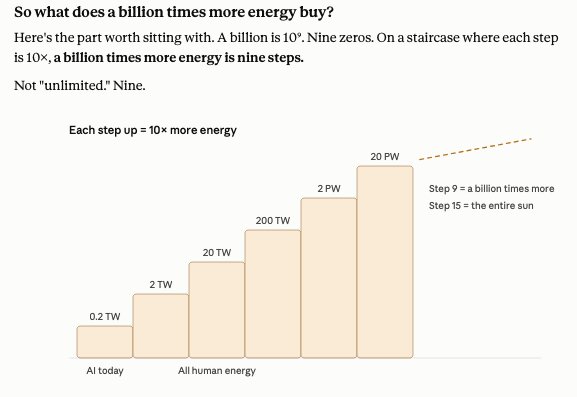
Capture every photon the Sun emits in every direction, build the full swarm, take Mercury apart to do it. This is about fifteen steps. That’s the ceiling of the entire solar system. Elon’s terawatt in orbit is roughly step four.
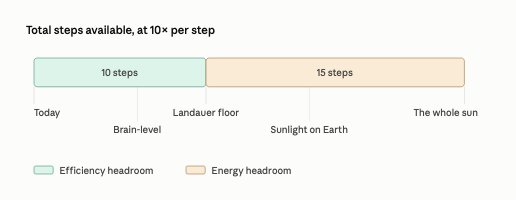
The brain is not the limit of efficiency
The brain’s ~10⁶ advantage is real, and it’s worth about six steps. But the brain is itself nowhere near the physical limit. A synaptic event dissipates something like 10⁴–10⁵ kT — roughly four orders of magnitude above the Landauer limit of kT ln2 ≈ 2.9 zeptojoules per bit erased at room temperature. Evolution optimized for a wet, self-repairing, 37 °C system built from proteins, not for thermodynamic optimality.
Efficiency budget stacks roughly like this:
about six steps from today’s silicon to brain-level, then about four more from brain-level down to Landauer. Call it ten steps total, with wide error bars.
Reversible computing evades the Landauer floor for logically reversible operations, but the adiabatic trade-off is brutal — dissipation falls roughly in proportion to how slowly you run, so you buy energy efficiency with time, which is the opposite of what a compute-hungry civilization wants. And the Margolus–Levitin and Bremermann bounds cap operations per joule and per kilogram regardless of cleverness.
Then the efficiency staircase is finished, and you are back to buying energy.
An efficiency step is a research result. It costs a lab, some years, and it applies retroactively to every watt you already own — a 10× algorithmic win makes your existing AI data center fleet ten times more capable as it is retrofitted. An energy step is 10× more physical plant with more turbines, transmission, launches, mirrors. It costs a decade and a continent, and it only applies going forward.
Brian Wang is a Futurist Thought Leader and a popular Science blogger with 1 million readers per month. His blog Nextbigfuture.com is ranked #1 Science News Blog. It covers many disruptive technology and trends including Space, Robotics, Artificial Intelligence, Medicine, Anti-aging Biotechnology, and Nanotechnology.
Known for identifying cutting edge technologies, he is currently a Co-Founder of a startup and fundraiser for high potential early-stage companies. He is the Head of Research for Allocations for deep technology investments and an Angel Investor at Space Angels.
A frequent speaker at corporations, he has been a TEDx speaker, a Singularity University speaker and guest at numerous interviews for radio and podcasts. He is open to public speaking and advising engagements.
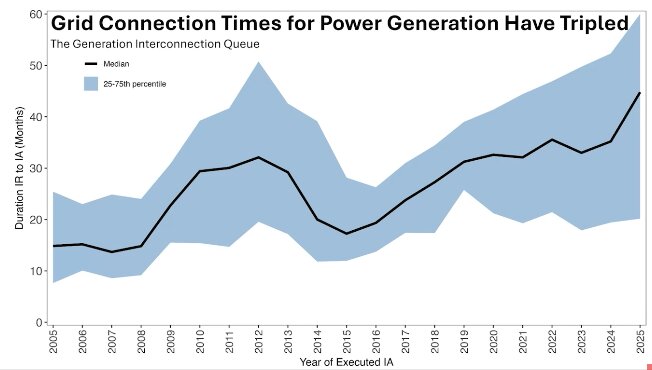
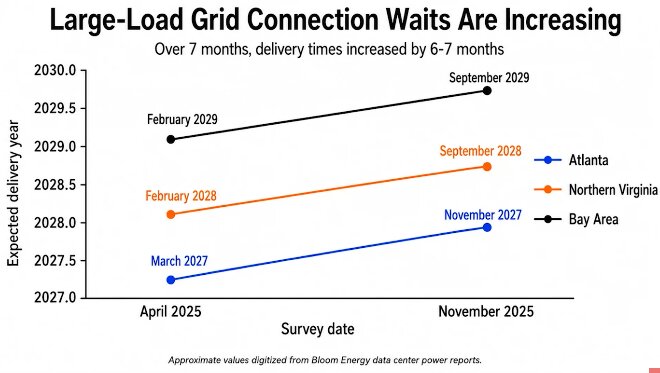
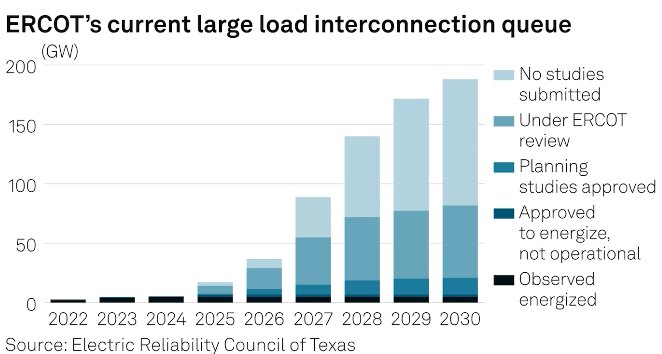
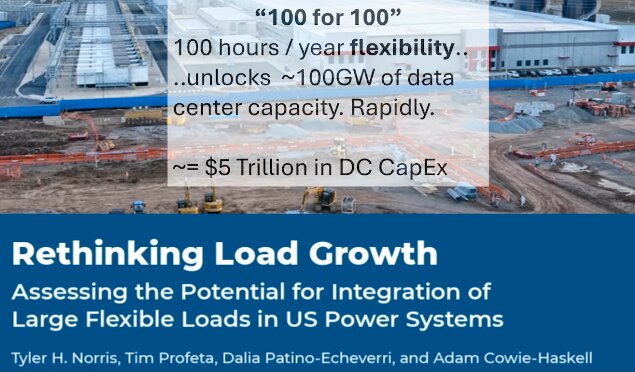
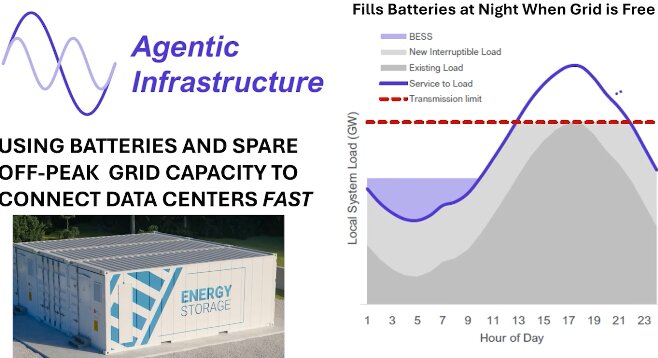
There’s a lot of maneuvering in Texas to tap natural gas and solar ‘behind the meter’, to avoid the bottleneck of ERCOT review and approval of a grid interconnection.
The next year will reveal just how fast Elon and competitors can build to self-supply a powerplant for data centers with no grid connection…