
Prime Agent is an open-source self-improving coding and research agent (harness) released by Prime Intellect on August 5, 2026. It is built for coding workflows and long-running autonomous tasks. It combines a Recursive Language Model (RLM) runtime with a Continual Harness, emphasizing token efficiency and expressiveness through programmatic tool calling, treating context as a variable, multi-agent messaging, and a self-modifiable harness state.
A language model on its own is just a text predictor. It can’t open files, run code, or browse anything. It only produces text. A harness is the software wrapped around the model that turns its text into real actions. The harness actually reads the file and pastes the contents back in. Claude Code and Codex are harnesses. Prime Agent is a competing one and it’s open-source.
It is available at https://github.com/PrimeIntellect-ai/prime-agent and installable via curl -fsSL https://app.primeintellect.ai/prime-agent/install.sh | sh. The primary announcement post is https://www.primeintellect.ai/blog/prime-agent.Core New CapabilitiesPrime Agent addresses limitations of conventional agent harnesses (fixed tool schemas, static sub-agents, lossy context compaction, and non-adaptable scaffolding).
Next Steps
Prime Agent is a new paradigm on the design of agent harnesses. Despite strong results over other harnesses, they still notice friction when running Prime Agent with models. This implies that there are huge performance gains still available from training with Prime Agent directly around this harness paradigm, or even the individual RLM and Continual Harness components.
They strongly believe that model-harness co-learning is the dominant paradigm to unlock new capabilities. Many features of Prime Agent are not fully utilized without a trained model, and they believe there are huge performance gains still available from training with the harness directly. They are excited to bring you these new capabilities, all in the open.
Core New Capabilities
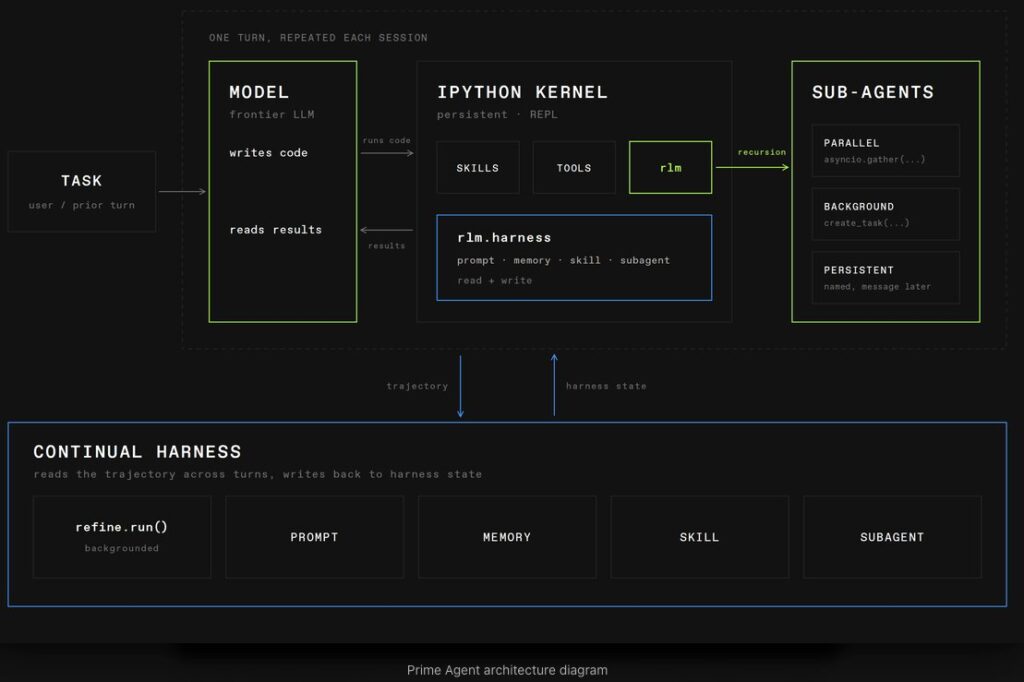
Prime Agent addresses limitations of conventional agent harnesses (fixed tool schemas, static sub-agents, lossy context compaction, and non-adaptable scaffolding). It rests on two abstractions plus supporting mechanisms:Recursive Language Model (RLM) + Programmatic Tool Calling + Context-as-Variable.
The model’s sole primary tool is a persistent IPython/REPL kernel. Context (prompts, history, data) is treated as Python variables rather than being stuffed into the model’s context window. The agent writes code to inspect, filter, transform, search, or decompose that state. Sub-agents and tools are invoked programmatically
Prime Agent is a general-purpose coding harness
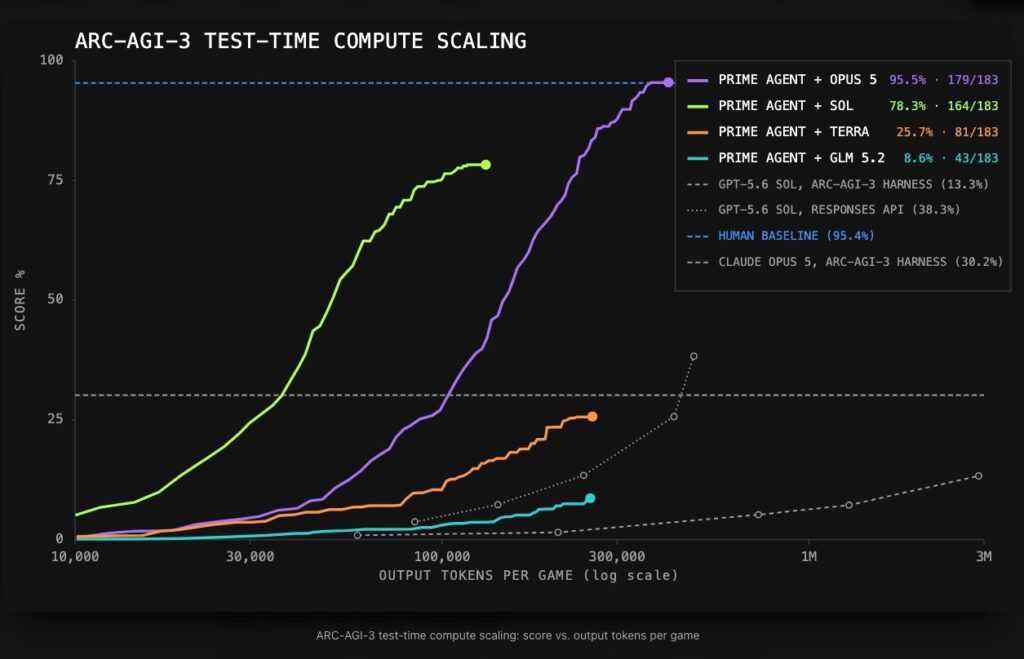
On ARC-AGI-3, it scores 95.5%, surpassing the human-expert baseline, but the gain is not benchmark-specific.
We see major improvements across models when compared to their proprietary harnesses: pic.twitter.com/Xa8zZiDtbF
— Prime Intellect (@PrimeIntellect) August 5, 2026
This is an evolution of the RLM paradigm introduced by Alex L. Zhang. Long inputs never need to enter the main model’s context window. The model can recursively spawn fresh LLM instances on snippets and keep useful state outside the active prompt. Compaction is programmatic and reversible. The design keeps the main model’s context small and focused while scaling work via code + sub-calls. This reduces context rot.
Multi-Agent Messaging and Orchestration
Sub-agents are full Prime Agent instances. They can run in parallel or background, persist across turns, and be messaged later via unique session IDs and agent-to-agent primitives. A daemon manages sessions, allowing detach/reattach, recovery, and “nuclear family” messaging (parent/sibling/child). This enables hierarchical or collaborative long-horizon work without routing everything through the user or a single context.
Self-Modifiable Continual Harness
The agent can perform CRUD operations on it mid-trajectory. The /refine command (or programmatic equivalent) reviews the trajectory, proposes small evidence-backed updates (a new skill, a memory note, or a refined sub-agent prompt), and applies them with snapshots for rollback. The base system prompt remains immutable. Skills are executable importable Python packages. A skill creator can package recurring workflows.
Related Continual Harness paper (cited by Prime Agent): https://arxiv.org/abs/2605.09998
Continual Harness: Online Adaptation for Self-Improving Foundation Agents (Karten, Zhang, et al.). Formalizes reset-free online CRUD refinement of harness state (prompt, sub-agents, skills, memory) from trajectory data within a single continuous run, demonstrated on long-horizon embodied tasks (Pokémon) and later applied to ARC-AGI-3-style settings.These pieces form a coherent research arc: Zhang’s RLM supplies the context-as-programmable-variable foundation.
Continual Harness supplies online self-modification of the scaffolding; Prime Agent operationalizes both into a practical, open coding/autonomous harness and demonstrates strong empirical results while inviting further RL co-training.
Brian Wang is a Futurist Thought Leader and a popular Science blogger with 1 million readers per month. His blog Nextbigfuture.com is ranked #1 Science News Blog. It covers many disruptive technology and trends including Space, Robotics, Artificial Intelligence, Medicine, Anti-aging Biotechnology, and Nanotechnology.
Known for identifying cutting edge technologies, he is currently a Co-Founder of a startup and fundraiser for high potential early-stage companies. He is the Head of Research for Allocations for deep technology investments and an Angel Investor at Space Angels.
A frequent speaker at corporations, he has been a TEDx speaker, a Singularity University speaker and guest at numerous interviews for radio and podcasts. He is open to public speaking and advising engagements.